
Web data platform
The web scraping APIthat handles the hard parts.
Send a URL, pick an engine, get structured data back. ScrapeNest manages proxies, retries, rendering, and extraction so you ship instead of babysitting scrapers.
Free to start. No credit card required.
3 engines/30 recipes/one endpoint/EU-only, hosted in France
HTTP, headless Chromium, and a fingerprint-hardened browser
same API for all three engines, typed SDKs for Python and TypeScript
hosted in France - scraped content never leaves the EU
credits per job by engine - you only pay when a job succeeds
What people actually scrape
The same three engines behind price tracking, competitive research, lead generation, and training data collection.
New · Recipes (beta)
Skip the scraper. Ask for the data.
Recipes are ready-made scrapers for well-known sites. Send a search query, a repository, or a channel, and get back JSON that matches a published schema. When the site changes, we fix the recipe. Your integration doesn't change.
- 30 recipes: Google, YouTube, Amazon, GitHub, Bluesky, Mastodon, Hacker News, news publishers, and more
- Every output is validated against its schema before you see it
- You pay only for definitive answers. Blocked, broken, or timed-out runs are free
Coming soon: write your own recipes in the same DSL and share them.
$ curl -X POST https://api.scrapenest.com/v1/recipes/hackernews-search/runs \
  -H "X-API-Key: $SCRAPENEST_API_KEY" \
  -d '{"input": {"q": "rust", "type": "show_hn"}}'

# GET /v1/jobs/{job_id}/result
{
  "recipe": { "slug": "hackernews-search", "contract": 1, "outcome": "ok" },
  "output": {
    "total_hits": 214,
    "results": [
      { "title": "Show HN: …", "points": 412, "comments": 96,
        "hn_url": "https://news.ycombinator.com/item?id=…" },
      …
    ]
  }
}
You send the URL. We handle the fetch.
One API call. We pick the right IP, render JavaScript if the page needs it, retry failures, and return the result.
Submit
POST a URL, pick an engine, add optional extraction rules. One API key, one endpoint.
We fetch
Clean egress IP, JavaScript rendering when needed, exponential backoff on transient failures. A job always finishes with a definite result - it never silently disappears into a queue.
You collect
Pull the result - HTML, JSON, screenshots, metadata - or let a signed webhook deliver it. Artifacts live in object storage under your retention policy.
Three ways to fetch a page
Same API, different execution cost. Start with Light at 1 credit. Reach for Stealth at 30 only when a site actively blocks you.
Light
HTTP (TLS impersonation)
Fast HTTP with browser-grade TLS fingerprints
No browser, no render cost. Mimics real browser TLS fingerprints and headers to pull JSON APIs and server-rendered HTML at volume.
APIs · static HTML · high volume
1 credit / job
Standard
Playwright + Chromium
Headless Chromium that runs the page's JavaScript
Renders SPAs, clicks, scrolls, paginates, fills forms, captures screenshots and HAR. The workhorse for JavaScript-heavy pages and flows behind a login.
SPAs · interactions · logged-in flows
5 credits / job
Stealth
Fingerprint-hardened browser
For sites with serious bot defenses
Fingerprint-hardened browser for Cloudflare, Akamai, DataDome. Use it when Standard gets blocked. 30 credits because it's the heaviest path.
Hostile targets · heavy anti-bot
30 credits / job
Structured output
You get more than the HTML.
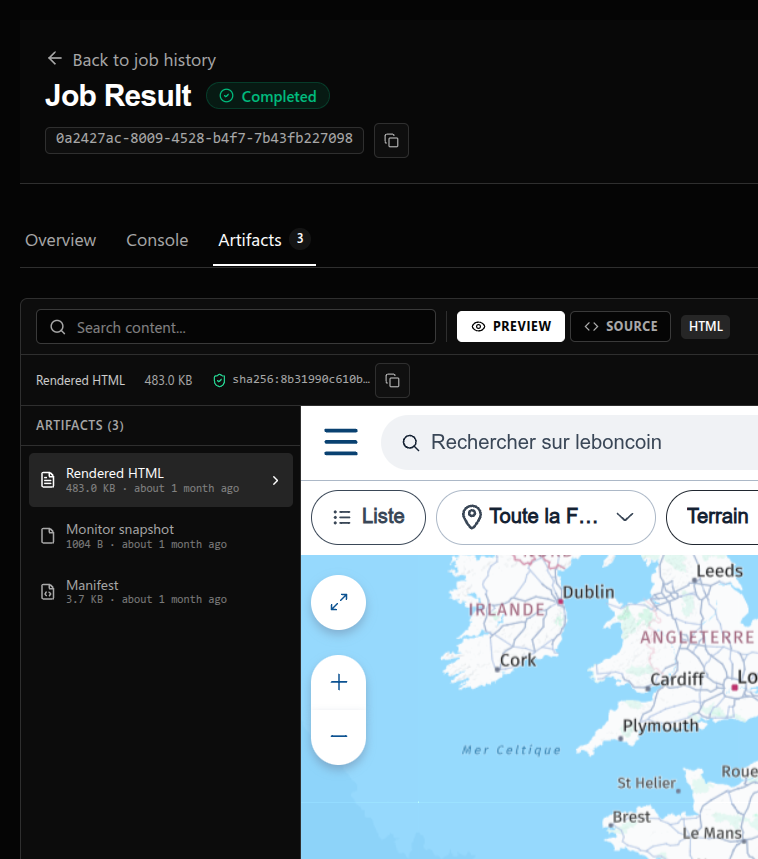
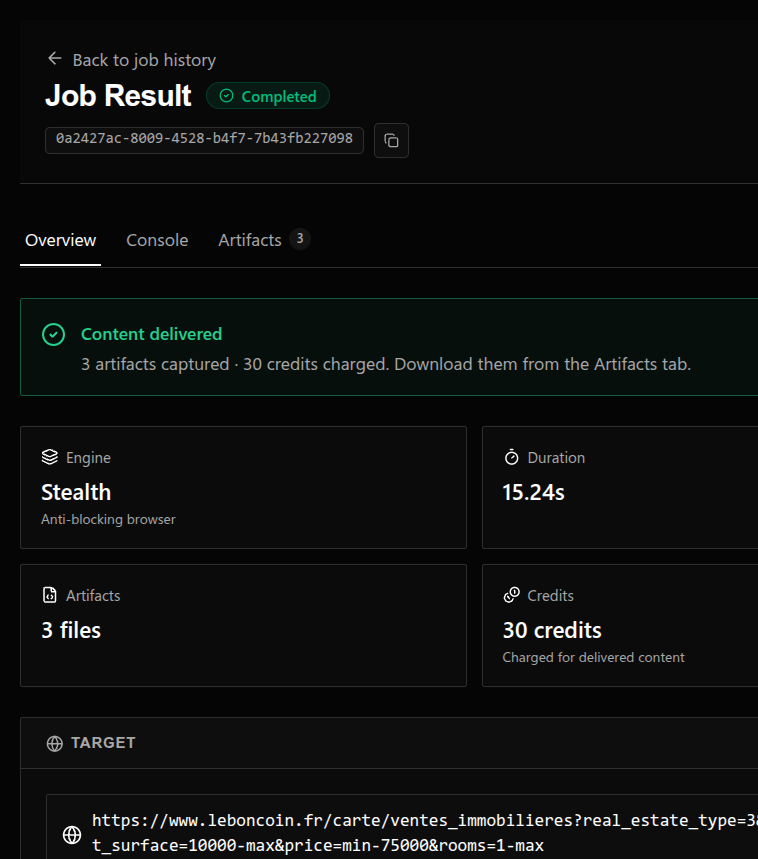
Every job returns a bundle: the rendered HTML, extracted JSON, a screenshot, response headers, and a signed manifest. When something looks off, replay the exact request and see what the browser saw.
- HTML, JSON, screenshot, and HAR in one response
- Engine, duration, status code, and timing breakdown per run
- Signed manifest with content hashes for audit and reproducibility
Monitoring & change detection
Watch a page. Know the moment it changes.
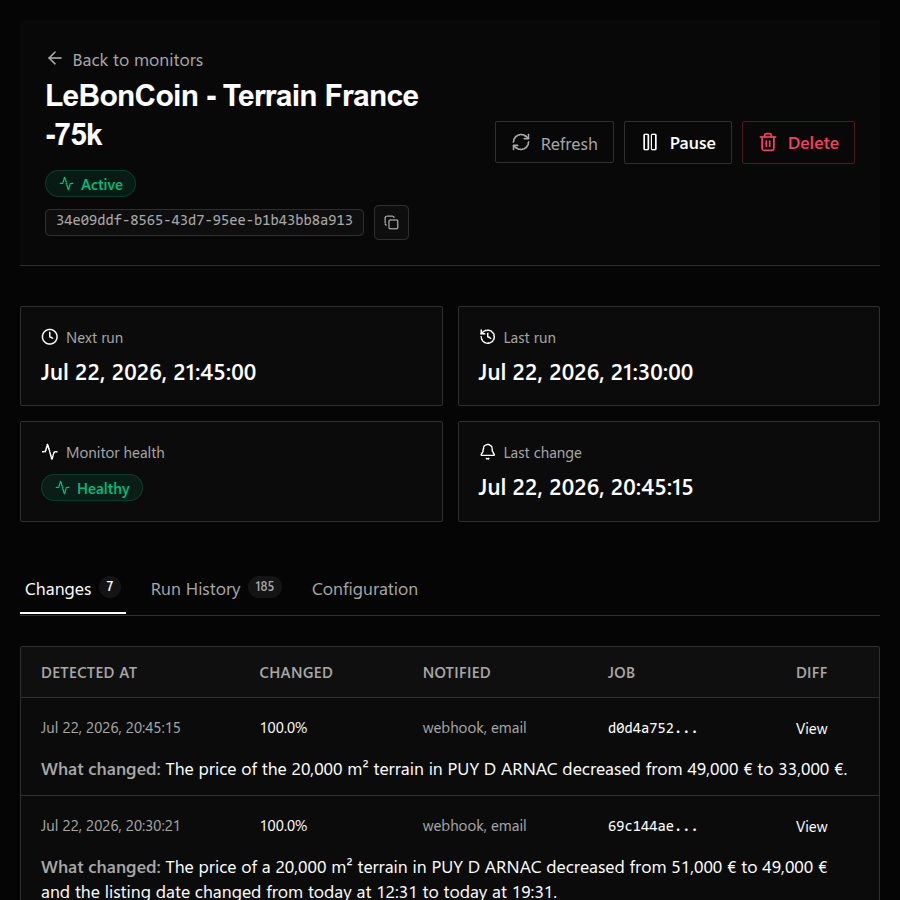
Give us a URL and a CSS selector. We check it on your schedule and tell you when the content changes, with a before/after diff and an AI summary of what changed.
- Cron-scheduled monitors, from every 5 minutes to daily
- Change detection on a CSS selector, full text, or extracted JSON fields
- Signed webhook and email with the diff the moment something moves
The boring infrastructure is already here
Retries, proxies, browser workers, delivery, observability. The parts that look trivial in a demo and eat a quarter in production.
Retries and failure handling
Exponential backoff, idempotent dispatch, dead-letter queue. Transient failures heal themselves. Permanent ones fail loudly with a reason.
JavaScript rendering
Pages that need Chromium are rendered automatically. Click, scroll, fill forms, wait for selectors. Stealth engine for sites that fight back.
Extraction in the job
Ship CSS, XPath, or JSONPath rules with the request. Structured JSON comes back with the result. No second pipeline to maintain.
Webhook delivery
Signed payloads, replay protection, automatic retries, delivery tracking. Wire it once.
Full request tracing
Per-job metrics, structured logs, and a request ID you can follow from API call to stored artifact.
OpenAPI and typed SDKs
Full spec, Python and TypeScript SDKs, and a console playground for the debug loop. Predictable errors, no surprises.